
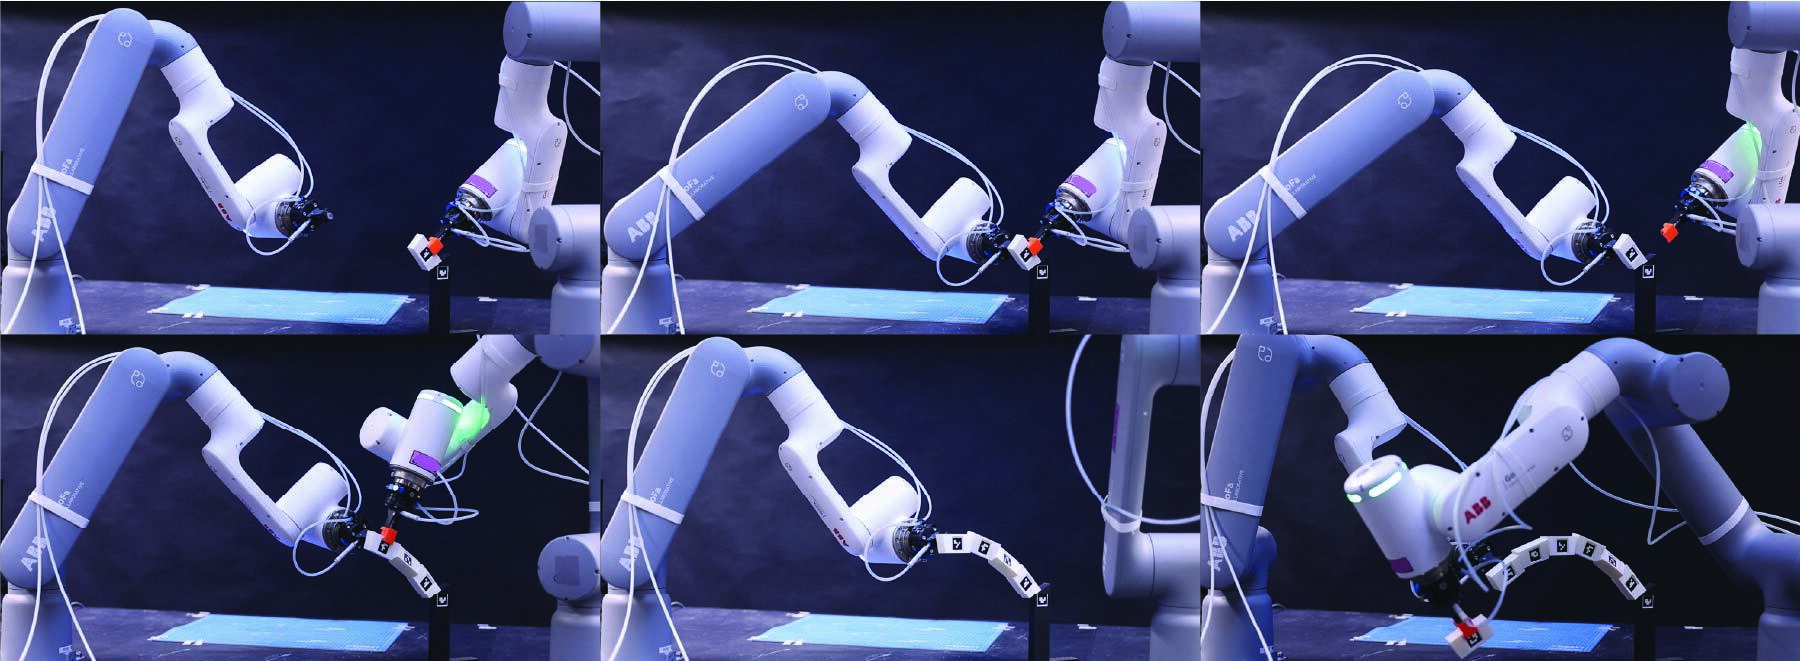
Figure 1: Construction process of the arch. The agent had to choose both the type of block (discrete) and where to place it (continuous). The second robot would simply hold the last block placed deterministically.
Motivation
Recently, we developed a variant of soft-actor critic (SAC) [1] to learn how to autonomously build an arch in a process shown in Figure 1 above — a task made complex by the mix of continuous and discrete actions. This algorithm vastly outperformed existing ones, such as hybrid PPO (HPPO)[2], but it might have been environment-dependent. Your objective is to answer this remaining question and to verify that the algorithm can be applied to different, more general, settings—such as RoboCup 2D, generally used to benchmark these hybrid-action-sets algorithms.
Your task
- Week 1-2: Getting familiar with the underlying theory and algorithms
- Week 3-4: Running HSAC on the original environment (doing robotic construction)
- Week 5-6: Finding a working implementation of other algorithms to compare it
- Week 7-8: Preparing for the midterm presentation
- Week 9-10: Being able to run all algorithms on a common benchmark
- Week 11-12: Getting results on the different trainings
- Week 13-14: Working on the final report
Background
Any interested student is advised to read [1] and [2] to get the required background, as well as our SAC variant implementation [3] to get an understanding of the algorithm they will have to adapt.
Requirements
A good knowledge of reinforcement learning is necessary. As the current implementation relies on graph neural networks (GNN), a background in this field is a plus. More generally, this project will be an applied coding project, so any course going in this direction is welcome. To apply for this project, please contact [email protected], and provide your CV and grade transcript.
References
[1] T. Haarnoja, A. Zhou, P. Abbeel, and S. Levine, “Soft actor-critic: Off-policy maximum entropy deep reinforcement learning with a stochastic actor,” in Proceedings of the 35th International Conference on Machine Learning, ICML 2018, Stockholmsmassan, Stockholm, Sweden, July 10-15, 2018 (J. G. Dy and A. Krause, eds.), vol. 80 of Proceedings of Machine Learning Research, pp. 1856–1865, PMLR, 2018.
[2] Z. Fan, R. Su, W. Zhang, and Y. Yu, “Hybrid actor-critic reinforcement learning in parameterized action space,” in Proceedings of the 28th International Joint Conference on Artificial Intelligence, IJCAI’19, p. 2279–2285, AAAI Press, 2019.
[3] G. Vallat, M. Kamgarpour, S. Parascho, “Learning to build covering structures with continuous adjustments”, Accepted in IROS 2026, https://infoscience.epfl.ch/handle/20.500.14299/265115